Skip to content
    Neurohive
    • News
    • Open LLMs
    • AI agents
    • Local models
    • Image & video
    RU

    Topics

    • Open LLMsOpen-weight models compared: quality, price and how to pick one
    • AI agentsAgents for coding, research and computer use: frameworks, benchmarks, comparisons
    • Image & videoImage and video generation and editing: models and services
    • Local modelsRunning models on your own hardware: VRAM, quantization, inference
    • AI basicsHow machine learning and neural networks work: explainers with formulas and Python code
    • BenchmarksWhat benchmarks measure and how to read launch-day numbers
    • World modelsWorld models, 3D scenes and robots: demos, code, what you can run
    • Proprietary modelsGPT, Gemini, Claude and other closed-weight models: pricing, tests, reviews
    • AI researchNew AI papers and models explained: what was proposed, the numbers, where the code is

    Sections

    • AI Apps
    • Datasets

    Neurohive

    • Contact Us
    News Open LLMs AI agents Image & video Local models AI basics Benchmarks World models Proprietary models AI research
    Neurohive
    News›

    Topics

    • Open LLMs
    • AI agents
    • Image & video
    • Local models
    • AI basics
    • Benchmarks
    • World models
    • Proprietary models
    • AI research

    Sections

    AI Apps Datasets

    Neurohive

    Contact Us
    Русский
    Home → Latest AI research: new models and papers explained → Page 5
    Topic

    Latest AI research: new models and papers explained

    22 September 2025 Image & video

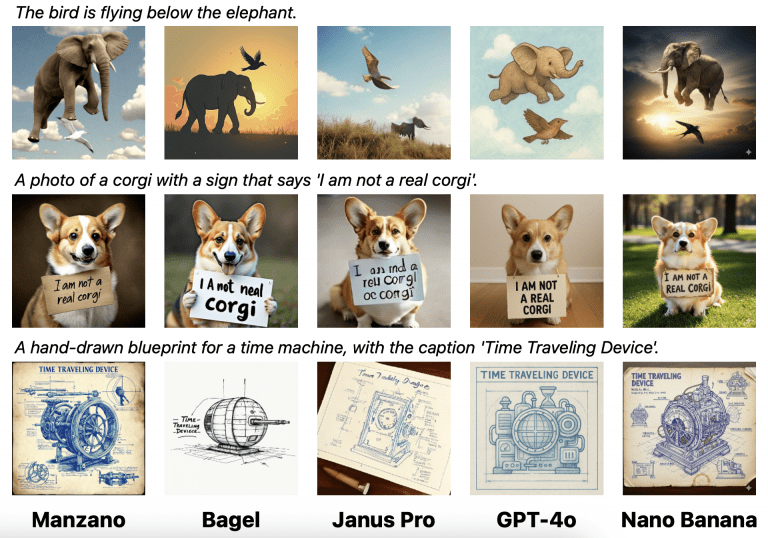
    Hybrid Image Tokenizer: Apple’s New Approach to Multimodal Models

    Apple Research Team introduced Manzano — a unified multimodal large language model that combines visual content understanding and generation capabilities through a hybrid image…
    10 September 2025 Open LLMs

    Mini-o3: A Multimodal 7B Model Outperformed GPT-4o in Visual Search With 30-Step Reasoning Chains

    Researchers from ByteDance and the University of Hong Kong introduced Mini-o3 — a multimodal model that performs deep multi-step reasoning to solve complex visual search tasks…

    26 August 2025 Image & video

    Google Launches Gemini 2.5 Flash Image with Text-Based Editing Capabilities

    Google introduced Gemini 2.5 Flash Image (with internal codename nano-banana) — a model for image generation and editing. The model supports combining multiple images into one…

    20 August 2025 Open LLMs

    NVIDIA Nemotron Nano 2: Reasoning and Code Generation Model Outperforms Qwen3-8B on Benchmarks and Supports 128k Context

    A team of NVIDIA researchers presented Nemotron-Nano-9B-v2 — a hybrid Mamba-Transformer language model that generates responses 6 times faster than Qwen3-8B on reasoning tasks…

    14 August 2025 World models

    Matrix-3D: Open Framework for Generating Fully Explorable 3D Worlds from a Single Image

    Researchers from Skywork AI and the Hong Kong University of Science and Technology have introduced Matrix-3D — a framework for creating fully explorable 3D worlds from a single…

    6 August 2025 World models

    3D-R1: Open Source Reasoning Model for 3D Scenes Outperforms State-of-the-Art Methods by 10% on 3D Benchmarks

    Researchers from Shanghai University of Engineering Science and Peking University presented 3D-R1 — a new foundation model that significantly improves reasoning capabilities in…

    6 August 2025 AI agents

    Seed Diffusion: New State-of-the-Art in Speed-Quality Balance for Code Generation Models

    The research team from ByteDance Seed in collaboration with the AIR Institute of Tsinghua University introduced Seed Diffusion Preview — a language model based on discrete…

    25 July 2025 Proprietary models

    Gemini 2.5 Pro Achieved Gold Medal Performance at IMO 2025, Solving 5 of 6 Problems

    Large language models perform well on mathematical benchmarks like AIME, however International Mathematical Olympiad (IMO) problems require deep understanding, creativity, and…

    11 July 2025 Image & video

    Show-o2: Open-source 7B multimodal model outperforms 14B models on benchmarks using significantly less training data

    Researchers from Show Lab at the National University of Singapore and ByteDance introduced Show-o2 — a second-generation multimodal model that demonstrates superior results in…

    15 June 2025 Open LLMs

    MiniCPM4: Open Local Model Achieves Qwen3-8B Performance with 7x Inference Acceleration

    The OpenBMB research team presented MiniCPM4 — a highly efficient language model designed specifically for local devices. MiniCPM4-8B achieves comparable performance to Qwen3-8B…

    4 June 2025 Open LLMs

    Strict On-Policy Training with Optimal Baseline: Microsoft Introduces Simplified Algorithm for RLHF

    The Microsoft Research team introduced On-Policy RL with Optimal reward baseline (OPO) — a simplified reinforcement learning algorithm for aligning large language models. The new…

    22 May 2025 AI agents

    Visual-ARFT: Multimodal AI Agents Outperform GPT-4o by 18.6% in Complex Visual Tasks

    A research team from Shanghai Jiao Tong University and Shanghai Artificial Intelligence Laboratory has introduced Visual Agentic Reinforcement Fine-Tuning (Visual-ARFT) — a new…

    ← Newer1…34567…20Older →
    Neurohive

    Neurohive — AI news. Open models, guides, reviews and comparisons.

    Topics

    • Open LLMs
    • AI agents
    • Image & video
    • Local models
    • AI basics
    • Benchmarks
    • World models
    • Proprietary models
    • AI research

    Sections

    • News
    • AI Apps
    • Datasets

    Neurohive

    • Contact Us
    • Русская версия
    • RSS
    © 2018–2026 Neurohive Neural network news and research