Skip to content
    Neurohive
    • News
    • Open LLMs
    • AI agents
    • Local models
    • Image & video
    RU

    Topics

    • Open LLMsOpen-weight models compared: quality, price and how to pick one
    • AI agentsAgents for coding, research and computer use: frameworks, benchmarks, comparisons
    • Image & videoImage and video generation and editing: models and services
    • Local modelsRunning models on your own hardware: VRAM, quantization, inference
    • AI basicsHow machine learning and neural networks work: explainers with formulas and Python code
    • BenchmarksWhat benchmarks measure and how to read launch-day numbers
    • World modelsWorld models, 3D scenes and robots: demos, code, what you can run
    • Proprietary modelsGPT, Gemini, Claude and other closed-weight models: pricing, tests, reviews
    • AI researchNew AI papers and models explained: what was proposed, the numbers, where the code is

    Sections

    • AI Apps
    • Datasets

    Neurohive

    • Contact Us
    News Open LLMs AI agents Image & video Local models AI basics Benchmarks World models Proprietary models AI research
    Neurohive
    News›

    Topics

    • Open LLMs
    • AI agents
    • Image & video
    • Local models
    • AI basics
    • Benchmarks
    • World models
    • Proprietary models
    • AI research

    Sections

    AI Apps Datasets

    Neurohive

    Contact Us
    Русский
    Home → Latest AI research: new models and papers explained → Page 3
    Topic

    Latest AI research: new models and papers explained

    14 May Image & video

    SenseNova-U1: NEO-unify multimodal architecture works directly with pixels without VAE

    SenseNova introduced a new multimodal architecture, SenseNova-U1, which combines image understanding, generation, and editing inside a single transformer without a separate…
    7 May AI agents

    OpenSeeker-v2: Best-in-Class Deep Research Agent Built by an Academic Team on Just 10,600 Samples

    Researchers from Shanghai Jiao Tong University have proven that building a best-in-class deep research agent doesn’t require hundreds of billions of pre-training tokens or…

    22 April AI agents

    OpenGame: AI Agent Generates Full Browser Games from Text Description

    A team of researchers from CUHK MMLab published OpenGame — the first agentic framework for creating browser-based 2D games from natural language descriptions. The project is…

    7 April Open LLMs

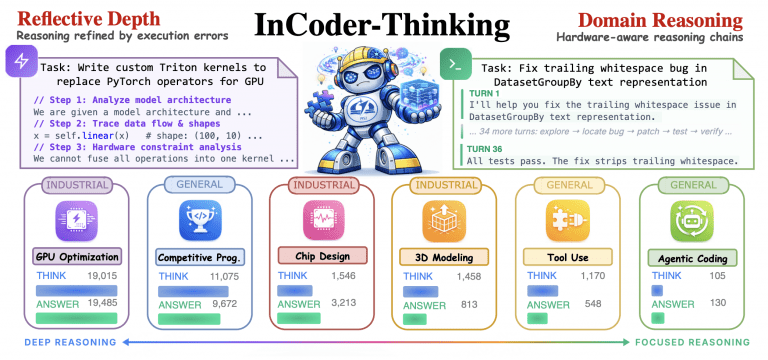
    InCoder-32B-Thinking: Open-Source Code Generation Model for Microcontrollers, GPU Kernel Optimization, and RTL Design

    A research team from Beihang University, Shanghai Jiao Tong University, the University of Manchester, and IQuest Research has published InCoder-32B-Thinking — a language model…

    3 April Open LLMs

    Trinity-Large-Thinking 400B: an open model matching Claude Opus-4.6 on agentic benchmarks at 28x lower price

    Arcee AI has released Trinity-Large-Thinking — an open-weight reasoning model for complex multi-turn agentic tasks. On PinchBench — a comprehensive benchmark for AI agents — it…

    31 March Image & video

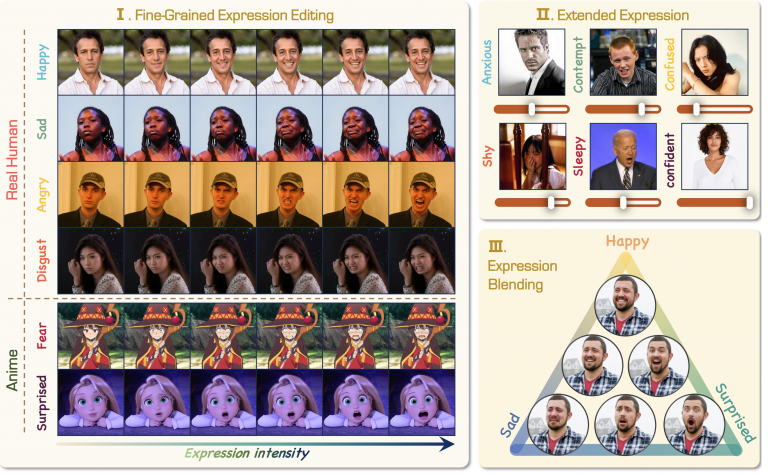
    PixelSmile: Open Model for Facial Expression Editing with Smooth Intensity Control

    Researchers from Fudan University and StepFun have published PixelSmile — a diffusion model for precise facial expression editing in portraits and anime images. Instead of…

    30 March Image & video

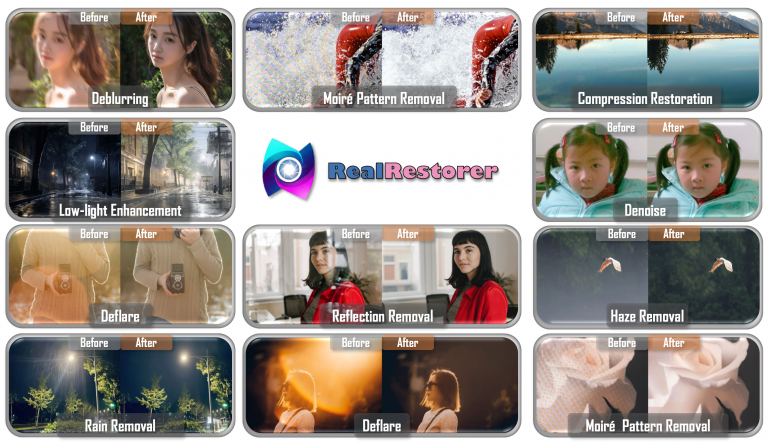
    RealRestorer: Open-Source Image Enhancement Model Outperforms Nano Banana Pro on Real-World Benchmark

    A team of researchers from StepFun, Southern University of Science and Technology, and the Chinese Academy of Sciences has published RealRestorer — an open-source image quality…

    27 March Open LLMs

    MinerU-Diffusion: A New Approach to OCR via Diffusion Decoding Speeds Up PDF Parsing 3× Without Accuracy Loss

    A team from Shanghai Artificial Intelligence Laboratory and Peking University published MinerU-Diffusion — a document OCR framework that abandons classical autoregressive…

    24 March Image & video

    daVinci-MagiHuman: Open 15B Model Generates a 5-Second Lip Sync Video in 2 Seconds on a Single H100

    SII-GAIR and Sand.ai have published daVinci-MagiHuman — an open-source multimodal 15B model based on a single-stream transformer that simultaneously generates video with precise…

    11 March Image & video

    Helios: 14B Model Generates Videos Longer Than 60 Seconds at 19.5 FPS on a Single H100

    A team of researchers from Peking University and ByteDance published Helios — an autoregressive diffusion transformer with 14 billion parameters that generates video at 19.5…

    10 February Open LLMs

    Baichuan-M3: An Open Medical Model That Conducts Consultations Like a Real Doctor and Outperforms GPT-5.2 on Benchmarks

    A research team from the Chinese company Baichuan has introduced Baichuan-M3 — an open medical language model that, instead of the traditional question-and-answer mode, conducts…

    22 January Benchmarks

    Claude Sonnet 4.5 Leads on Comprehensive Backend Benchmark, Outperforming in Both Code and Environment Configuration

    A team of researchers from Fudan University and Shanghai Qiji Zhifeng Co. introduced ABC-Bench — the first benchmark that tests the ability of AI agents to solve full-fledged…

    ← Newer12345…20Older →
    Neurohive

    Neurohive — AI news. Open models, guides, reviews and comparisons.

    Topics

    • Open LLMs
    • AI agents
    • Image & video
    • Local models
    • AI basics
    • Benchmarks
    • World models
    • Proprietary models
    • AI research

    Sections

    • News
    • AI Apps
    • Datasets

    Neurohive

    • Contact Us
    • Русская версия
    • RSS
    © 2018–2026 Neurohive Neural network news and research