Linus Torvalds Had Claude Code Speed Up Linux File Reads by Up to 23x. A Human Found the Critical Bug It Missed

20 October 2026
torvalds-claude-code-linux

Linus Torvalds Had Claude Code Speed Up Linux File Reads by Up to 23x. A Human Found the Critical Bug It Missed

Linux kernel developers are still debating how far to trust code written by AI. Meanwhile, Linux creator Linus Torvalds asked Anthropic’s AI agent Claude Code to tackle a problem that…
GPT-6-Astra Has Crossed the Threshold of Embodied Competence, but Not Embodied Intelligence. A SenseNova Study

19 October 2026

GPT-6-Astra Has Crossed the Threshold of Embodied Competence, but Not Embodied Intelligence. A SenseNova Study

The SenseNova team, together with ACE Robotics, Ropedia, Nanyang Technological University, and the University of Tokyo, published a study that checks whether OpenAI’s GPT-6-Astra has achieved embodied intelligence. Here, embodied…

Building a Private RAG Pipeline with a Local LLM: A Practical Guide for Developers (2026)

13 October 2026
Building a Private RAG Pipeline with a Local LLM A Practical Guide for Developers

Building a Private RAG Pipeline with a Local LLM: A Practical Guide for Developers (2026)

To build a private Retrieval-Augmented Generation (RAG) pipeline, generate vector embeddings locally using an open-source model, store them in an on-premise vector database, and query a quantized local LLM over…

Kimi K3 Review: Moonshot AI’s Architecture, Benchmarks, Open Weights, and Fable 5 Comparison

3 August 2026
kimi k3

Kimi K3 Review: Moonshot AI’s Architecture, Benchmarks, Open Weights, and Fable 5 Comparison

Moonshot AI has released Kimi K3, the first open model in the 3-trillion-parameter class, with a 1-million-token context window. It is already available in the Kimi chatbot and through the…

TurboVLA: Robot Gets Commands Several Times Faster at a 97% Success Rate Thanks to Swapping the LLM for BERT

3 August 2026
TurboVLA model robot munipulation

TurboVLA: Robot Gets Commands Several Times Faster at a 97% Success Rate Thanks to Swapping the LLM for BERT

Researchers from Huazhong University of Science and Technology and Huawei have released TurboVLA, a compact vision-language-action model that produces robot actions in 31.2 ms on a consumer-grade RTX 4090 and…

Bonsai 27B: 1-Bit Weights Put a 27B-Parameter Model on a Smartphone for the First Time

15 July 2026
Bonsia 27B 1-bit

Bonsai 27B: 1-Bit Weights Put a 27B-Parameter Model on a Smartphone for the First Time

PrismML, a startup founded by Caltech researchers, has announced Bonsai 27B — binary and ternary versions of the Qwen3.6-27B model that retain 90–95% of the original model’s quality while compressing…

Claude Sonnet 5: A Strong Agentic Upgrade, but No Clear Opus Replacement

1 July 2026
claude sonnet 5 new

Claude Sonnet 5: A Strong Agentic Upgrade, but No Clear Opus Replacement

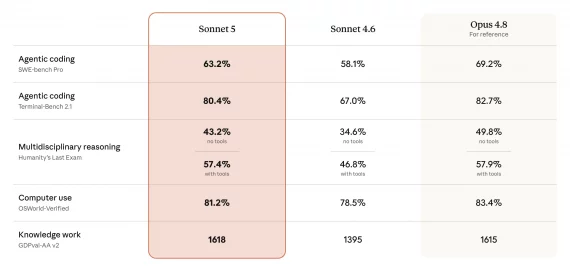
Anthropic has introduced Claude Sonnet 5, a new model in the Claude family that is also available to users on the free tier. It is designed for agentic tasks, programming,…

LFM2.5-230M: An Ultra-Compact Model Runs on a Raspberry Pi and Almost Any Modern Phone

29 June 2026
liquid AI

LFM2.5-230M: An Ultra-Compact Model Runs on a Raspberry Pi and Almost Any Modern Phone

Liquid AI released LFM2.5-230M — one of the smallest language models out there today, at just 230 million parameters. It’s compact enough to run on a small device without trouble:…

VibeThinker: 3B model reasons and codes at the level of flagship models

16 June 2026
https://neurohive.io/ru/ii-v-marketinge/pochemu-socseti-blokirujut-67-multiakkaunterov-v-pervye-3-dnya-analiz-500-otchetov/

VibeThinker: 3B model reasons and codes at the level of flagship models

Sina Weibo AI published VibeThinker-3B — a compact language model with just 3 billion parameters that matches flagship models DeepSeek V3.2 (671B), GLM-5 (744B), and Gemini 3 Pro on verifiable…

ESM Cambrian: protein language model outperformed Google’s AlphaFold3 and built the largest atlas of the protein world

4 June 2026
esm model

ESM Cambrian: protein language model outperformed Google’s AlphaFold3 and built the largest atlas of the protein world

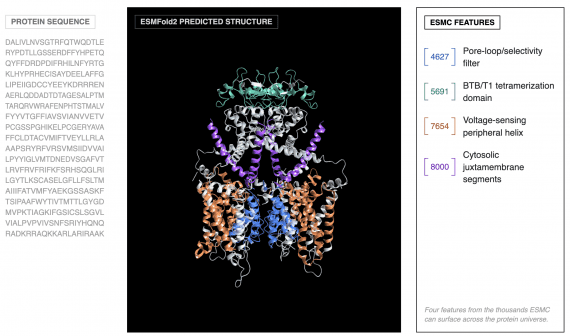
A team of researchers from Biohub published ESM Cambrian (ESMC) — a language model for protein structure prediction and design that outperformed AlphaFold3 by Google on structure prediction accuracy, designed…

OpenAI Codex Beginner’s Guide: Setup, Workflows, and Pricing

18 May 2026
OpenAI codex guide for beginners

OpenAI Codex Beginner’s Guide: Setup, Workflows, and Pricing

AI coding tools have changed dramatically over the past two years. Early assistants like GitHub Copilot mostly worked as advanced autocomplete systems — useful for speeding up repetitive coding, but…

OpenSeeker-v2: Best-in-Class Deep Research Agent Built by an Academic Team on Just 10,600 Samples

7 May 2026
OpenSeeker-v2

OpenSeeker-v2: Best-in-Class Deep Research Agent Built by an Academic Team on Just 10,600 Samples

Researchers from Shanghai Jiao Tong University have proven that building a best-in-class deep research agent doesn’t require hundreds of billions of pre-training tokens or expensive reinforcement learning. Just 10,600 carefully…

Trinity-Large-Thinking 400B: an open model matching Claude Opus-4.6 on agentic benchmarks at 28x lower price

3 April 2026
Trinity AI models foundation

Trinity-Large-Thinking 400B: an open model matching Claude Opus-4.6 on agentic benchmarks at 28x lower price

Arcee AI has released Trinity-Large-Thinking — an open-weight reasoning model for complex multi-turn agentic tasks. On PinchBench — a comprehensive benchmark for AI agents — it ranks second among all…

GLM-5: Top-1 Open-Weight Model for Code and Text Generation, Competing with Claude and GPT on Agentic Tasks

19 February 2026

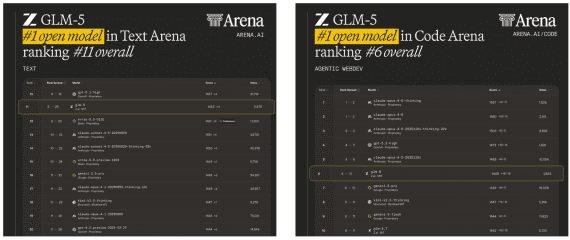
GLM-5: Top-1 Open-Weight Model for Code and Text Generation, Competing with Claude and GPT on Agentic Tasks

Zhipu AI and Tsinghua University have published a GLM-5 technical report — currently the top-performing open-weight language model by benchmarks: first place among open-weight models on Artificial Analysis and top-1…

Baichuan-M3: An Open Medical Model That Conducts Consultations Like a Real Doctor and Outperforms GPT-5.2 on Benchmarks

10 February 2026
Baichuan-M3

Baichuan-M3: An Open Medical Model That Conducts Consultations Like a Real Doctor and Outperforms GPT-5.2 on Benchmarks

A research team from the Chinese company Baichuan has introduced Baichuan-M3 — an open medical language model that, instead of the traditional question-and-answer mode, conducts a full clinical dialogue, actively…

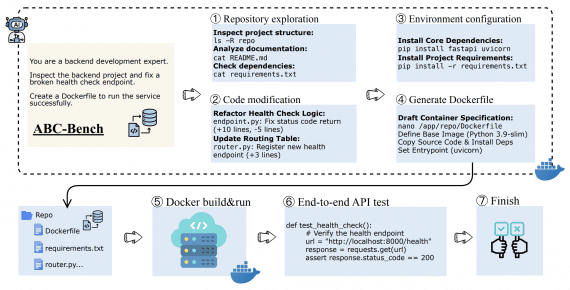
Claude Sonnet 4.5 Leads on Comprehensive Backend Benchmark, Outperforming in Both Code and Environment Configuration

22 January 2026
abc-bench-pipeline-workflow

Claude Sonnet 4.5 Leads on Comprehensive Backend Benchmark, Outperforming in Both Code and Environment Configuration

A team of researchers from Fudan University and Shanghai Qiji Zhifeng Co. introduced ABC-Bench — the first benchmark that tests the ability of AI agents to solve full-fledged backend development…

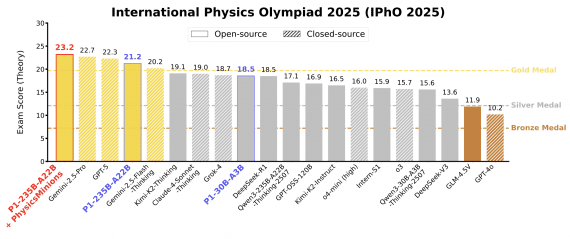
P1: First Open-Source Model to Win Gold at the International Physics Olympiad

30 November 2025

P1: First Open-Source Model to Win Gold at the International Physics Olympiad

P1-235B-A22B from Shanghai AI Laboratory became the first open-source model to win a gold medal at the latest International Physics Olympiad IPhO 2025, scoring 21.2 out of 30 points and…

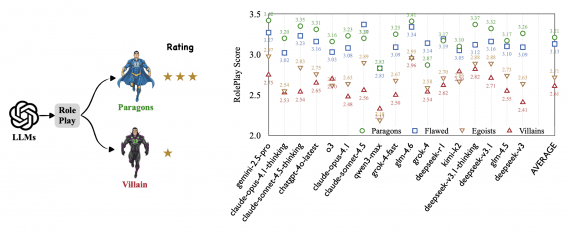
Which AI Can Play a Villain: Comparing Alignment Algorithms Across 17 ModelsRetry

13 November 2025

Which AI Can Play a Villain: Comparing Alignment Algorithms Across 17 ModelsRetry

Researchers from Tencent Multimodal Department and Sun Yat-Sen University published a study on how large language models handle role-playing. It turns out that AI models perform mediocrely at role-playing: even…

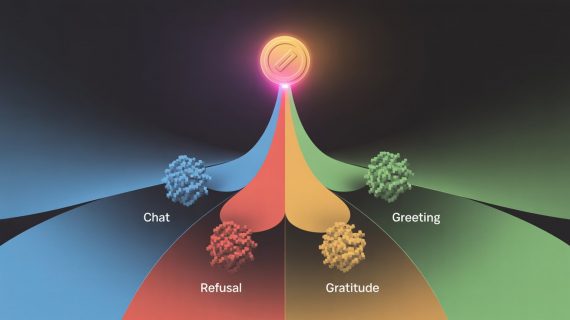
From Millions Spent on “Thank You” to Efficient Inference: Boilerplate Detection in a Single Token

31 October 2025
Detecting Boilerplate Responses LLM

From Millions Spent on “Thank You” to Efficient Inference: Boilerplate Detection in a Single Token

Researchers from JFrog published a study demonstrating a method for early detection of boilerplate responses in large language models after generating just a single token. The method enables computational cost…

Kimi-K2 and Qwen3-235B-Ins – Best AI Models for Stock Trading, Chinese Researchers Found

10 October 2025
stocks trading with AI

Kimi-K2 and Qwen3-235B-Ins – Best AI Models for Stock Trading, Chinese Researchers Found

Researchers from China conducted a large-scale comparison of AI capabilities for stock trading using real market data. AI agents managed a portfolio of 20 Dow Jones Index stocks over 4…

Hybrid Image Tokenizer: Apple’s New Approach to Multimodal Models

22 September 2025
manzano

Hybrid Image Tokenizer: Apple’s New Approach to Multimodal Models

Apple Research Team introduced Manzano — a unified multimodal large language model that combines visual content understanding and generation capabilities through a hybrid image tokenizer and carefully designed training strategy.…