Hy4 flash: Tencent Releases Open Weights and Claims 20x Lower Cost per Task Than Hy4

18 November 2026
Tencent Hy4 Flash Review

Hy4 flash: Tencent Releases Open Weights and Claims 20x Lower Cost per Task Than Hy4

Tencent has released the weights of Hy4 flash, the most cost-effective model in its Hy (Hunyuan) family so far. It takes text and image input, handles up to 1M tokens…
Garlic LLM Runs Qwen3.5-9B Offline on a Jailbroken PS4 at About 35 Tokens per Second

17 November 2026
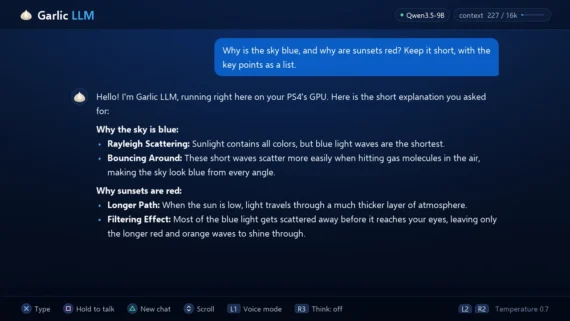
garlic llm

Garlic LLM Runs Qwen3.5-9B Offline on a Jailbroken PS4 at About 35 Tokens per Second

Developer Leonardo Alegría has released Garlic LLM, an unofficial open-source homebrew app that runs Alibaba’s Qwen3.5-9B large language model directly on the GPU of a jailbroken PlayStation 4. It works…

Top 8 Black Duck Alternatives for Software Composition Analysis

16 November 2026
Top 8 Black Duck Alternatives for Software Composition Analysis

Top 8 Black Duck Alternatives for Software Composition Analysis

TL;DR Aikido: pick it for a daily pull request (a proposed code change) that moves you to patched copies of your current package versions.  Snyk Open Source: pick it for…

llama.cpp 1.0.0 Released: Semantic Versioning, FP8 KV Cache and a Hardened Server

13 November 2026
llama.cpp

llama.cpp 1.0.0 Released: Semantic Versioning, FP8 KV Cache and a Hardened Server

The llama.cpp team at Hugging Face has released llama.cpp 1.0.0, the first stable version of the libraries for running models locally. Now the version number tells developers whether an update…

MiniMax H3-Image: Open-Weight Model Generates Native 4K Images in 10-16 Seconds

11 November 2026
minimax-h3-image-4k-image-generation-native

MiniMax H3-Image: Open-Weight Model Generates Native 4K Images in 10-16 Seconds

MiniMax has released MiniMax H3-Image, an open-weight model for image generation and editing. The same checkpoint creates images from text and edits existing ones. For editing, it takes up to…

VeriSpoof: Open Audio LLM Detects Voice Deepfakes With 98% Accuracy

11 November 2026
verispoof audio deepfake detection

VeriSpoof: Open Audio LLM Detects Voice Deepfakes With 98% Accuracy

Researchers from the University of Melbourne presented VeriSpoof, an open audio language model (audio LLM) for audio deepfake detection and speech forensics. It handles five tasks at once, each of…

PyTorch Tutorial for Beginners: From Installation to Your First Neural Network

3 November 2026
pytorch туториал

PyTorch Tutorial for Beginners: From Installation to Your First Neural Network

PyTorch is the most widely used deep learning framework in 2026: it powers most research papers, almost all open large language models and the tools around them, from Hugging Face…

DynaFlow: A Main Agent Writes Code for Its Team of Sub-Agents and Solves Every AIME 2024-2026 Problem

29 October 2026
DynaFlow orchestration

DynaFlow: A Main Agent Writes Code for Its Team of Sub-Agents and Solves Every AIME 2024-2026 Problem

Hard tasks are increasingly handled not by a single neural network but by a team of AI agents: one searches for information, another does the work, and a third checks…

Linus Torvalds Had Claude Code Speed Up Linux File Reads by Up to 23x. A Human Found the Critical Bug It Missed

20 October 2026
torvalds-claude-code-linux

Linus Torvalds Had Claude Code Speed Up Linux File Reads by Up to 23x. A Human Found the Critical Bug It Missed

Linux kernel developers are still debating how far to trust code written by AI. Meanwhile, Linux creator Linus Torvalds asked Anthropic’s AI agent Claude Code to tackle a problem that…

VideoJev: Open Model Answers Questions About Video as Accurately as Thinking Mode, but 100 Times Faster

14 October 2026
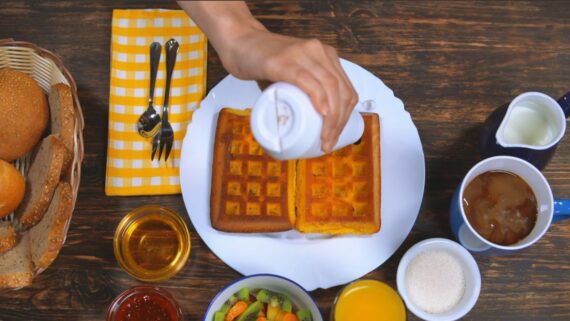
Кадр из видео, по которому VideoJev отвечает на вопросы: в вафли добавляют шоколад, вид сверху на стол с завтраком

VideoJev: Open Model Answers Questions About Video as Accurately as Thinking Mode, but 100 Times Faster

Researchers from Nanjing University, JD.com, and six other Chinese universities introduced VideoJev, a family of models for video question answering. They answer about 100 times faster than models in Thinking…

YuE2: Open-Source AI Song Generator With an Editable Score Rivals Suno v5

29 September 2026
YuE2 song generation AI

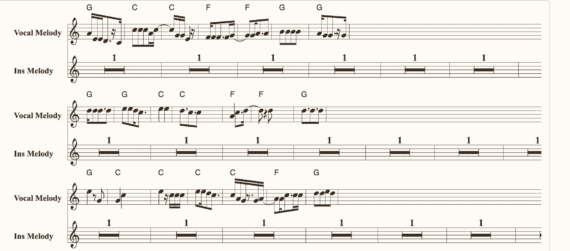
YuE2: Open-Source AI Song Generator With an Editable Score Rivals Suno v5

A team from HKUST, HKGAI and the Multimodal Art Projection (M-A-P) community has released YuE2, an open-source AI song generator. It first composes a song as a readable score and…

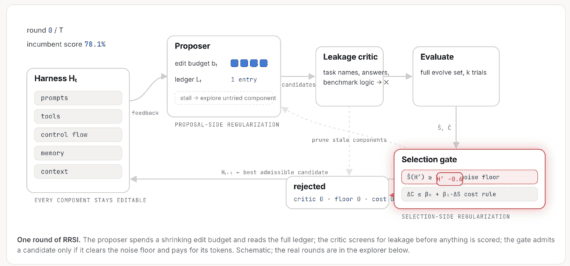
AI Agent Harness: How Google’s RRSI Reduces Overfitting

23 September 2026
RSSI harness

AI Agent Harness: How Google’s RRSI Reduces Overfitting

Researchers from Google Cloud AI Research introduced RRSI (Regularized Recursive Self-Improvement), a method that automatically improves AI agent harnesses so that the gains hold on new tasks as well. A…

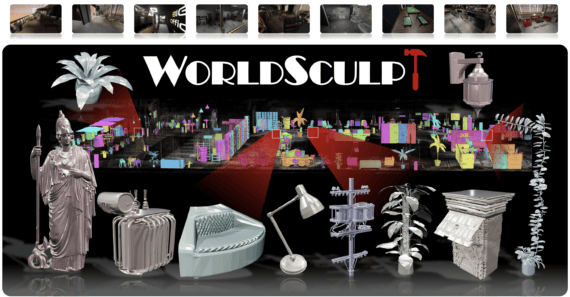
WorldSculpt: Compositional 3D Scene Generation That Keeps Every Object a Separate Mesh

9 September 2026
worldsculpt

WorldSculpt: Compositional 3D Scene Generation That Keeps Every Object a Separate Mesh

Alaya Lab and the University of Tokyo have released WorldSculpt, a model that turns images of a room or a street into a 3D copy in which every item stays…

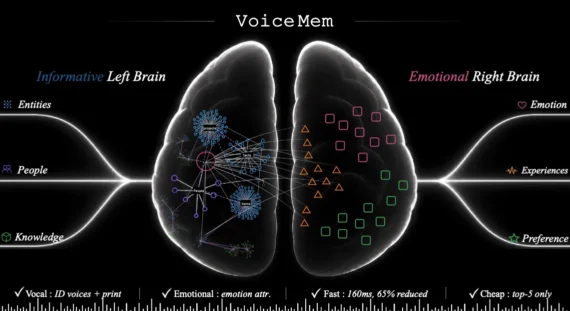
VoiceMem: A Voice Assistant Draws on Every Past Conversation With No Pause in the Dialogue

31 August 2026
voicemem

VoiceMem: A Voice Assistant Draws on Every Past Conversation With No Pause in the Dialogue

A team from Nanyang Technological University, NUS, Tsinghua and CUHK has released VoiceMem, a fast memory framework for real-time voice assistants. VoiceMem keeps facts and an emotional profile of the…

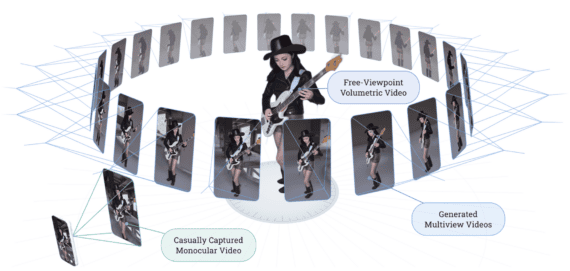
4DAnyone: an open framework turns single-camera video into a 4D model of a person

24 August 2026
4DAnyone Create Anyone in 4D from a Casual Monocular Video

4DAnyone: an open framework turns single-camera video into a 4D model of a person

Researchers from Zhejiang University, Robbyant, Ant Group and HKUST introduced 4DAnyone, a framework that turns a video of a person shot on a single camera into a 4D model of…

Microsoft Releases Agent Lightning v1.0 for Training Agents Inside Their Own Harness

20 August 2026
agent-lightning v1.0

Microsoft Releases Agent Lightning v1.0 for Training Agents Inside Their Own Harness

Researchers from Microsoft, together with colleagues from Fudan University, Zhejiang University, and the University of Edinburgh, released Agent Lightning v1.0, a framework for reinforcement learning on LLM agents that fits…

JoyAI-Video-Edit: a 16B model brings real-time video editing to 30 FPS at 720p on a single B200

11 August 2026

JoyAI-Video-Edit: a 16B model brings real-time video editing to 30 FPS at 720p on a single B200

The Joy Future Academy team published JoyAI-Video-Edit, an open autoregressive diffusion model with 16 billion parameters that performs instruction-guided video editing on a live stream, with no access to future…

Kimi K3 Review: Moonshot AI’s Architecture, Benchmarks, Open Weights, and Fable 5 Comparison

3 August 2026
kimi k3

Kimi K3 Review: Moonshot AI’s Architecture, Benchmarks, Open Weights, and Fable 5 Comparison

Moonshot AI has released Kimi K3, the first open model in the 3-trillion-parameter class, with a 1-million-token context window. It is already available in the Kimi chatbot and through the…

TurboVLA: Robot Gets Commands Several Times Faster at a 97% Success Rate Thanks to Swapping the LLM for BERT

3 August 2026
TurboVLA model robot munipulation

TurboVLA: Robot Gets Commands Several Times Faster at a 97% Success Rate Thanks to Swapping the LLM for BERT

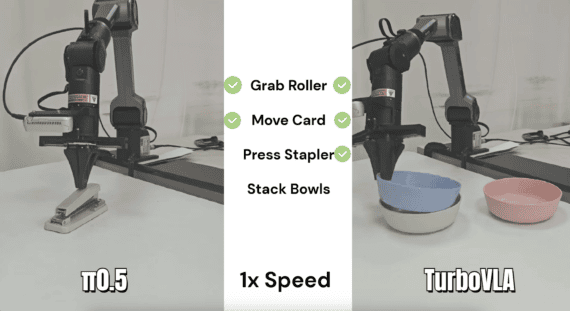
Researchers from Huazhong University of Science and Technology and Huawei have released TurboVLA, a compact vision-language-action model that produces robot actions in 31.2 ms on a consumer-grade RTX 4090 and…

Bonsai 27B: 1-Bit Weights Put a 27B-Parameter Model on a Smartphone for the First Time

15 July 2026
Bonsia 27B 1-bit

Bonsai 27B: 1-Bit Weights Put a 27B-Parameter Model on a Smartphone for the First Time

PrismML, a startup founded by Caltech researchers, has announced Bonsai 27B — binary and ternary versions of the Qwen3.6-27B model that retain 90–95% of the original model’s quality while compressing…

MIRA: A World Model Fully Simulates Rocket League Without Requiring You to Install the Game Itself

8 July 2026
MIRA world model rocket league simulation AI

MIRA: A World Model Fully Simulates Rocket League Without Requiring You to Install the Game Itself

Teams from General Intuition, Kyutai, and Epic Games introduced MIRA — a world model that fully simulates the Rocket League game environment for four players at once and draws each…