Vidu S2: The Model Generates Video Avatars at 720p and 25–42 FPS and Edits Streams in Real Time

19 September 2026
Vidu S2

Vidu S2: The Model Generates Video Avatars at 720p and 25–42 FPS and Edits Streams in Real Time

Researchers from Tsinghua University and Shengshu Technology have introduced Vidu S2, two video models that let you build a digital avatar and hold a video call with it or run…
JoyAI-Video-Edit: a 16B model brings real-time video editing to 30 FPS at 720p on a single B200

11 August 2026

JoyAI-Video-Edit: a 16B model brings real-time video editing to 30 FPS at 720p on a single B200

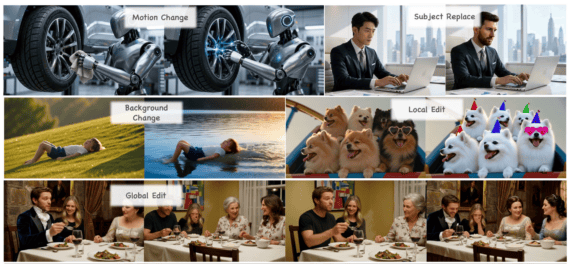
The Joy Future Academy team published JoyAI-Video-Edit, an open autoregressive diffusion model with 16 billion parameters that performs instruction-guided video editing on a live stream, with no access to future…

MIRA: A World Model Fully Simulates Rocket League Without Requiring You to Install the Game Itself

8 July 2026
MIRA world model rocket league simulation AI

MIRA: A World Model Fully Simulates Rocket League Without Requiring You to Install the Game Itself

Teams from General Intuition, Kyutai, and Epic Games introduced MIRA — a world model that fully simulates the Rocket League game environment for four players at once and draws each…

Trinity-Large-Thinking 400B: an open model matching Claude Opus-4.6 on agentic benchmarks at 28x lower price

3 April 2026
Trinity AI models foundation

Trinity-Large-Thinking 400B: an open model matching Claude Opus-4.6 on agentic benchmarks at 28x lower price

Arcee AI has released Trinity-Large-Thinking — an open-weight reasoning model for complex multi-turn agentic tasks. On PinchBench — a comprehensive benchmark for AI agents — it ranks second among all…

PixelSmile: Open Model for Facial Expression Editing with Smooth Intensity Control

31 March 2026
PixelSmile

PixelSmile: Open Model for Facial Expression Editing with Smooth Intensity Control

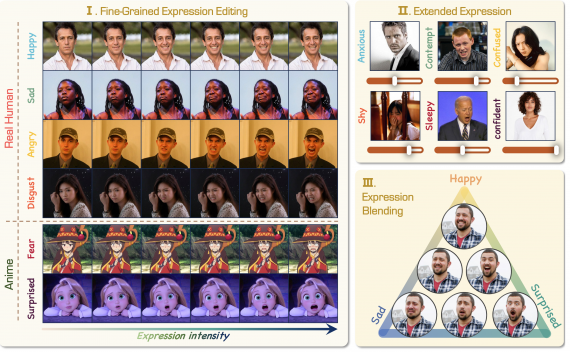
Researchers from Fudan University and StepFun have published PixelSmile — a diffusion model for precise facial expression editing in portraits and anime images. Instead of training on discrete labels like…

RealRestorer: Open-Source Image Enhancement Model Outperforms Nano Banana Pro on Real-World Benchmark

30 March 2026
Realresorer image restoration open model 2

RealRestorer: Open-Source Image Enhancement Model Outperforms Nano Banana Pro on Real-World Benchmark

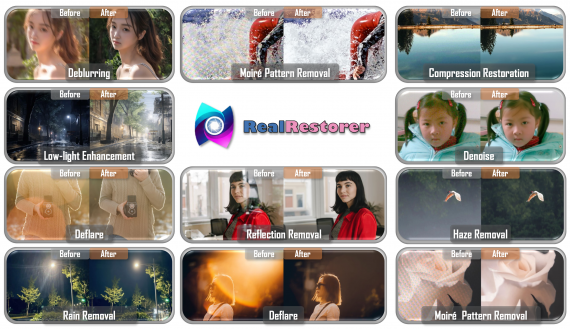
A team of researchers from StepFun, Southern University of Science and Technology, and the Chinese Academy of Sciences has published RealRestorer — an open-source image quality enhancement model that removes…

MinerU-Diffusion: A New Approach to OCR via Diffusion Decoding Speeds Up PDF Parsing 3× Without Accuracy Loss

27 March 2026
Miner-U-Diffusion

MinerU-Diffusion: A New Approach to OCR via Diffusion Decoding Speeds Up PDF Parsing 3× Without Accuracy Loss

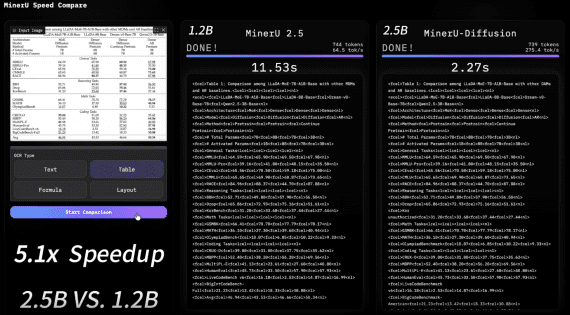
A team from Shanghai Artificial Intelligence Laboratory and Peking University published MinerU-Diffusion — a document OCR framework that abandons classical autoregressive generation in favor of diffusion-based decoding. The project is…

Helios: 14B Model Generates Videos Longer Than 60 Seconds at 19.5 FPS on a Single H100

11 March 2026

Helios: 14B Model Generates Videos Longer Than 60 Seconds at 19.5 FPS on a Single H100

A team of researchers from Peking University and ByteDance published Helios — an autoregressive diffusion transformer with 14 billion parameters that generates video at 19.5 frames per second on a…

Seed Diffusion: New State-of-the-Art in Speed-Quality Balance for Code Generation Models

6 August 2025
seed diffusion

Seed Diffusion: New State-of-the-Art in Speed-Quality Balance for Code Generation Models

The research team from ByteDance Seed in collaboration with the AIR Institute of Tsinghua University introduced Seed Diffusion Preview — a language model based on discrete diffusion that demonstrates record-breaking…

Sora: OpenAI’s Groundbreaking Text-to-Image Diffusion Model

18 February 2024
openai sora

Sora: OpenAI’s Groundbreaking Text-to-Image Diffusion Model

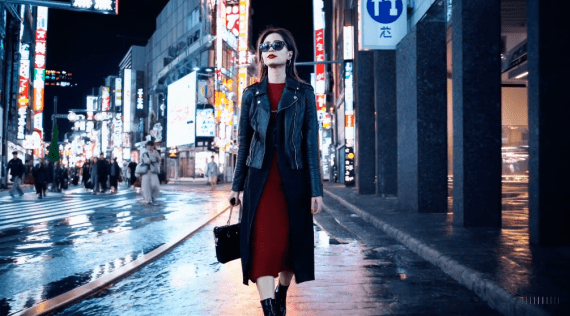
OpenAI has unveiled Sora, a diffusion-based text-to-image model capable of generating 60-second videos. Compared to competitors like Runway, Pika, Stability AI, and Google, OpenAI’s model boasts high-resolution (Full HD) output,…

Google MobileDiffusion: Generating Images on Mobile Devices

4 February 2024
MobileDiffusion

Google MobileDiffusion: Generating Images on Mobile Devices

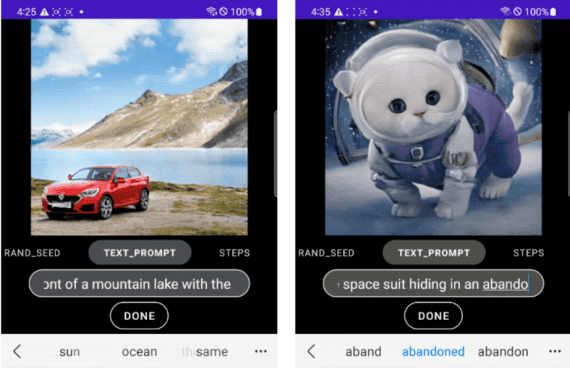
Google has introduced MobileDiffusion, a real-time text-to-image generation model that operates entirely on mobile devices. On Android and iOS devices with the latest generation processors, image generation at a resolution…

Diffusion Model Trained to Predict Chemical Reactions

27 December 2023
mit duffusion model

Diffusion Model Trained to Predict Chemical Reactions

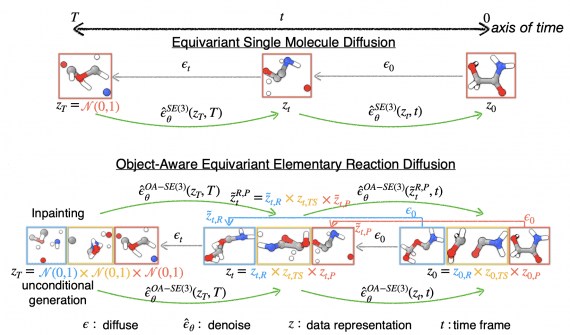
MIT scientists have developed a model that predicts the likelihood of a molecule reaching a transition state—critical for determining the probability of a chemical reaction. Furthermore, researchers will use the…

Google Try-on: Try Clothes Virtually with Realistic Models

18 June 2023
нейросеть одежда

Google Try-on: Try Clothes Virtually with Realistic Models

Google has introduced Try-on, a diffusion model that allows users of the “Shopping” service to try on clothes on models with different body types and skin tones. With just one…

Uncrop: AI Image Outpainting Online with Stable Diffusion XL

11 June 2023
uncrop stablilityai

Uncrop: AI Image Outpainting Online with Stable Diffusion XL

Uncrop is an AI neural network that draws outpainting images in your browser using the specifically fine-tuned Stable Diffusion XL model. The model analyzes the content of the uploaded image…