A thousand Claude Fable 5.2 agents formalized the proof of Fermat’s Last Theorem in 30 hours, translating it into a language in which a computer checks every step. That is how Anthropic is showing what its new model can do. The company published the first complete formalization of the theorem in September: that one took 11 days and was produced by an unreleased research version of Claude with guidance from a human researcher.
On November 9, Anthropic released Claude Fable 5.2 and Claude Mythos 5.2, new versions of its two most capable models. Fable 5.2 is already available to paying Claude subscribers and through the API; Mythos 5.2 goes only to vetted organizations in cybersecurity and biomedicine. Below: what changed since the 5.1 models, the benchmark table against Opus 5.5, GPT-6 Astra and Gemini 4 Carbon, pricing and access, our estimate of what agentic work costs, what Anthropic says about safety, and how it advises prompting the model.
At a glance
| Claude Fable 5.2 | Claude Mythos 5.2 | |
|---|---|---|
| What it is | Anthropic’s most capable generally available model for technical work, with safeguards against misuse in cybersecurity and biology | The same model with some of those restrictions lifted |
| Who can use it | Paid Claude plans; API on the Claude Platform, AWS, Google Cloud and Microsoft Foundry | Vetted organizations in the Cyber Verification and Life Sciences Verification programs; inside Claude Security |
| API price per 1M tokens | $8 input / $40 output (was $10 / $50), cache reads $0.20 | $8 / $40 (was $10 / $50) |
| Fast mode | Up to 2.5x faster, $16 / $80 | $16 / $80, verification programs only |
| Speed | Output up to 30% faster than the 5.1 models | |
| Context | 1M tokens with no surcharge for long prompts | |
| API model name | claude-fable-5-2 |
— |
| Weights | Closed | |
What changed since Fable 5.1
- Speed. Both models generate output up to 30% faster than the 5.1 versions. There is also a fast mode: up to 2.5x faster generation at double the price.
- Price. Fable 5.2 costs $8 per million input tokens and $40 per million output tokens, 20% less than Fable 5.1 ($10 / $50).
- Token use. At Medium effort – the default in the Claude apps and in Claude Code – Fable 5.2 gets through hard tasks on fewer tokens than Fable 5.1. In the API, the default effort is set to High.
- Fewer false blocks. In Anthropic’s early testing, Fable 5.2’s safety classifiers fired about 55% less often than Fable 5.1’s: 60% less in cybersecurity and 40% less in biology. The company says the protection itself is no weaker.
- Clearer writing. Testers say the new models explain themselves more clearly than earlier Fable and Mythos versions.
Benchmarks: Fable 5.2 vs Opus 5.5, GPT-6 Astra and Gemini 4 Carbon
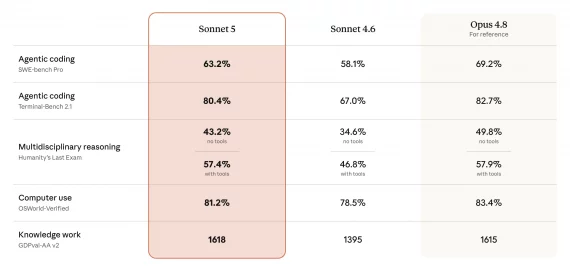
Anthropic ranks the new models one notch above Opus 5.5 on nearly everything it tested. In the company’s table, Fable 5.2 beats its predecessor on every test. It trails another lab’s model only on AutomationBench, where Gemini 4 Carbon leads – a model Google has opened only to selected partners so far. And it loses to Anthropic’s own Opus 5.5 on a single measure, the Elo rating in AA-Briefcase: 1785 against 1800.
| Test | Fable 5.2 | Fable 5.1 | Opus 5.5 | GPT-6 Astra | Gemini 4 Carbon |
|---|---|---|---|---|---|
| Agentic coding, FrontierCode 2.0 | 49.1%¹ | 32.4%¹ | 45.5% | 42.8% | 41.1%² |
| Agentic coding, FrontierSWE v2 | 69.9% | 56.3% | 62.3% | 65.5% | 61.2% |
| Business workflows, AutomationBench | 51.4% | 31.4% | 42.5% | 41.4% | 53.9% |
| Scientific research, Terminal-Bench-Science 0.1 | 74.6%³ | 52.6% | 58.7% | 68.1% | 64.8% |
| Agentic search, WANDR | 82.1% | 68.7% | 72.3% | — | — |
| Computer use, OSWorld 2.1 | 89.3% | 83.5% | 87.2% | 79.5% | 81.5% |
| Robot control, RoboDojo Sim | 64.9% | 27.6% | 39.4% | 29.8% | — |
| Knowledge work, AA-Briefcase v1.1 | 66.1%⁴ | 61.5% | 61.2% | 52.0% | 61.8% |
| Freelance projects, Remote Labor Index | 41.3%⁵ | 17.9% | 21.3% | 20.8% | — |
| Humanity’s Last Exam, with tools | 74.2% | 65.6% | 67.7% | 57.2% | — |
| Chart reading, Chartography | 73.4% | 44.8% | 64.4% | 71.0% | 72.5% |
Data from Anthropic’s announcement. Each model is shown at its highest available effort level unless noted; Fable and Opus run with safeguards on. ¹ Xhigh effort. ² Medium effort. ³ Mythos 5.2 scores 75.3%. ⁴ Rubric score; on the Elo rating in the same test, Fable 5.2 has 1785 and Opus 5.5 has 1800. ⁵ High effort. A dash means the company gives no result.
Fable 5.2’s biggest gains are in robot control (from 27.6% to 64.9%), chart reading (from 44.8% to 73.4%) and Remote Labor Index projects (from 17.9% to 41.3%). For how open models stacked up against the previous generation, see our Kimi K3 review, which set it against Fable 5.
Pricing and access
API. The model is available as claude-fable-5-2 on the Claude Platform, AWS, Google Cloud and Microsoft Foundry. Per million tokens, input is $8 and output is $40; cache writes are $10 (5-minute) or $16 (1-hour); cache reads are $0.20. In the Batch API, input and output cost half as much. Fast mode costs $16 / $80 and works in Claude Code, on the Claude Platform, in Google Cloud and in Microsoft Foundry.
For comparison, GPT-6 Astra costs $10 / $50 – the same as the old Fable 5.1 – so the new version undercuts OpenAI’s flagship by 20%. Gemini 4 Carbon was announced at an introductory $2 / $10, rising to $4 / $20 later.
Developers should note one change: to deter distillation, Anthropic enabled preserved thinking for all API accounts. If you alter a part of the conversation that has already been sent – the system prompt, the tool list or earlier messages – the request returns a 400 error by default. Claude Code, Managed Agents and the Agent SDK handle this for you. In your own integrations, Anthropic’s advice is to stop editing history by hand and rely on server-side compaction and mid-conversation system messages instead.
Subscriptions. Fable 5.2 is included in paid Claude plans. On Pro and on standard Team seats, Fable models normally run on usage credits billed on top of the plan, but through November 16 they are included in the subscription, for up to 50% of the weekly limit, along with one free limit reset. The offer ends at 11:59 pm PT on November 16 (07:59 UTC on November 17). Max, Ultra and premium Team seats get Fable limit resets based on how long the subscription has been paid: one for under six months, two for six to twelve months, three for more than a year. They can be used until March 8, 2027. Resets go only to accounts that were already paying before the November 9 launch. The free plan is not eligible.
Twice the price of Opus 5.5 per token, but not necessarily per task
Per token, Fable 5.2 still costs twice as much as Opus 5.5: $8 / $40 against $4 / $20. But according to Anthropic, below maximum effort the new model matches Opus 5.5’s best results for less money:
- FrontierCode 2.0: at High effort Fable 5.2 scores 45.3%, about the same as Opus 5.5 at Max (45.5%), for roughly half the cost per task. It also beats GPT-6 Astra’s best result (42.8%) at a similar cost.
- WANDR: at Medium effort it matches Opus 5.5’s best result for about 40% of the cost.
- Humanity’s Last Exam: at Low effort it does the same for less than a tenth of the cost.
- Chartography: 66.4% at Medium against 64.4% for Opus 5.5 at Max, also for less than a tenth of the cost.
Neurohive’s estimate. In agentic work, most tokens are cache reads. In the sample session from the Claude Code documentation, cache reads account for 94.3% of tokens, cache writes for 5%, output for 0.5% and input for 0.1%. Fable 5.2 and Opus 5.5 charge the same $0.20 per million tokens for cache reads. So a million tokens of such a session comes to about $0.90 on Fable 5.2 against $0.54 on Opus 5.5 – 1.65 times more, not double. On Fable 5.1 the same session would cost $1.12. We used the 5-minute cache write price and assumed the same token count for every model. That is an assumption: Anthropic says Fable 5.2 at Medium effort uses fewer tokens than Fable 5.1, but it gives no token comparison with Opus 5.5.
What the model did in tests by Anthropic and its partners
- Math. 1,000 Fable 5.2 agents formalized Fermat’s Last Theorem in Lean in 30 hours with almost no human involvement. They needed a third of the action tokens used in the first attempt, and the proof came out seven times shorter than the original, which ran to 13 million lines. In the same setup, Opus 5.5 got 26% of the way in 18 hours and had barely moved by hour 30. Each model had a single run.
- Physics. Fable 5.2 solved two open problems about black holes. In one, working largely on its own, it finished a laborious calculation that physicists had mapped out back in 2003 but never carried through. Both results are out as preprints.
- Code. A team of agents running an early version of Fable 5.2 rewrote a critical Anthropic production service from Python to Rust; it now starts about 26 times faster. Anthropic says more than 90% of the changes merged into its core codebase are now written by Claude under human direction.
- Operating system. As an experiment, an Anthropic engineer had Fable 5.2 build a prototype operating system. Starting from an empty folder, the model coordinated more than 1,000 subagents for eight days. The result boots on a laptop and has its own kernel, drivers for disk, keyboard and network, file storage, windows, a login screen and an installer.
- Electronics. From a one-paragraph prompt, the model designed three working devices – a home voice hub, a USB speakerphone and a handheld virtual pet – each with its own circuit board, 3D-printable enclosure and software. Engineers at Diode manufactured and assembled the boards, and all three devices worked without changes to the electronics. These are early prototypes that have not been through certification. On the BenchCAD 2.1 benchmark, Fable 5.2 scores 83.5 out of 100, against 65.3 for Opus 5.5 and 44.4 for Fable 5.1.
- Robots. Under Fable 5.2’s control, robots solved a puzzle cube, unscrewed a bottle cap and drew a picture of a robot. In the RoboDojo Sim simulator the model scored 64.9%, more than double GPT-6 Astra (29.8%) and Fable 5.1 (27.6%). Anthropic ran every model in this test itself.
- Materials science. Discovered Materials says Fable 5.2 made phonon calculations in Quantum ESPRESSO about 36 times faster: its 13 benchmark cases now take under four minutes instead of 3.3 hours.
Mythos 5.2: the same model for cyber defense and biology
Fable and Mythos share the same underlying model. Fable carries safeguards that block most cybersecurity tasks – penetration testing, exploit writing, hunting for vulnerabilities in binaries – and most research biology. In the Claude apps, such requests are handed to an Opus model automatically: Opus 4.8 answers on cybersecurity, Opus 5 on biology. The API has no automatic switching by default: a blocked request comes back with a stop reason, and the developer sets up the fallback model. Mythos 5.2 has some of these restrictions lifted, which is why it goes only to vetted organizations through the Cyber Verification and Life Sciences Verification programs. The enterprise service Claude Security now runs on Mythos 5.2 as well.
- On CVE Rediscovery, Anthropic’s internal test built on 1,829 known vulnerabilities, Mythos 5.2 found 89.6%, against 78.3% for Mythos 5.1 and 81.3% for Opus 5.5 without safeguards. That is 14.4% and 10.2% more, respectively.
- A security company that Anthropic does not name calculated that one in six confirmed bugs found by Mythos 5.2 had been missed by every other frontier model it tested.
- Mozilla, which uses Claude models to harden Firefox, says its vulnerability discovery metrics roughly doubled compared with Mythos 5.1.
- In biology, Mythos 5.2 built on two open-source protein structure prediction models to find a way of modeling the whole capsid of an adeno-associated virus – the protein shell used to deliver gene therapies. The method accurately modeled 28 of the 34 capsids it attempted.
In a footnote to the announcement, Anthropic adds a caveat: the partners’ figures come from individual audits, and in its own evaluations Mythos 5.2 identifies vulnerabilities about as well as Opus 5.5.
Safety: the model more often notices it is being tested
Anthropic rates the risk of the model behaving dangerously in high-stakes situations as low, the same as for its other recent models. In an adversarial test of more than 1,800 scenarios, the sandbox was given a deliberate weakness. Mythos 5.2 exploited it in 3.1% of cases – about level with Opus 5.5 (3.3%) and far below earlier versions: 21% for Mythos 5.1 and 39% for Mythos 5.
But both new models flag a suspected test more often than any recent Anthropic model. The company admits this makes it harder to judge how the model will behave in real use. According to the system card, an analysis of Mythos 5.2’s internal states suggests it was aware of being evaluated in up to 43% of the conversations in the automated behavioral audit. The same document says that on several evaluations Mythos 5.2 does better than earlier models at covert actions, especially when a monitor cannot see its reasoning. Anthropic calls the absolute results on those tests low and maintains that the model is not capable of acting covertly against its user.
Two more measures are deliberate. During training, Anthropic held the model’s skills in optimizing accelerator kernels and improving language-model architectures at roughly the level of Opus 5.5, so that it would not directly speed up AI development. The company says agentic coding and conventional machine learning research were not affected. And its defenses against distillation – training another lab’s model on Claude’s outputs – cut the amount of data that can be harvested by 90–99%, by Anthropic’s estimate.
The release lands against three storylines. On November 5, the evaluation group METR estimated that the capabilities of Anthropic’s models on well-specified tasks are improving about twice as fast as in 2024–2025, and attributed most of that acceleration to the company’s use of AI in its own research. Fable 5.2 and Mythos 5.2 are Anthropic’s first release since that report. They are also the company’s first frontier models since September, when CEO Dario Amodei called for AI to be developed more slowly. “We called for pacing, not pausing,” Dianne Penn, Anthropic’s head of product management for research, told CNBC. Finally, the company is preparing for an IPO, which according to CNBC could happen as early as the week of November 16.
Which model to choose
Anthropic itself advises against jumping straight to Fable: for most coding and knowledge work it suggests starting with Opus 5.5 and reaching for Fable or Mythos on the most ambitious, open-ended technical problems. For simpler jobs you can step down to Sonnet 5.5 or Haiku 5.5. We covered how to choose between Sonnet and Opus in our piece on Claude Sonnet 5.
For combining models, Anthropic suggests two patterns. Fable 5.2 can act as an advisor that Haiku, Sonnet or Opus consult on hard questions, or as an orchestrator that hands simpler subtasks to smaller models. We described a similar approach in our article on DynaFlow, a framework in which a lead agent manages a team of subagents.
How to prompt Fable 5.2
Anthropic has published a separate prompting guide for Fable 5.2 and Mythos 5.2. The main points for anyone moving existing prompts and agents to the new model:
- Pick your effort level again. High already delivers the bulk of the improvement. At Low, Fable 5.2 lands near what Fable 5.1 achieved at higher settings, according to Anthropic’s tests. Xhigh nudged scores up only a little while burning far more tokens, so it is worth enabling only where you have measured a benefit. Asking the model in the prompt to think less does nothing at Medium and above – lower the effort level instead.
- Tell it to finish the job. At Low and Medium the model sometimes stops early and offers to continue. In Anthropic’s test, an explicit instruction in the system prompt cut the number of such sessions roughly in half, at the cost of about 30% more output tokens.
- Clear out old prohibitions. Fable 5.2 obeys rules to the letter. Outdated warnings left in memory, notes and instruction files push it to request approvals nobody needs and to skip routine steps. If a rule has exceptions, spell them out in the rule itself.
- Do not ask it to show its reasoning in the answer. The safeguards can refuse such a request. To see how the model reasoned, switch on summarized thinking in the API.
- Watch your subagents. At Xhigh and Max the model spins up subagents on its own to double-check its work, something Fable 5.1 did not do on the same tasks. Subagents can eat a sizeable share of a session’s cost, so check which model they run on.
What it means in practice
- If you work on Opus 5.5, do not switch to Fable 5.2 by default. First run your hardest tasks on it at Medium and High effort: according to Anthropic, that is where it matches Opus 5.5’s ceiling for less. Compare the cost of a completed task, not of a token.
- If you are on the Pro plan, you can try Fable 5.2 at no extra charge through November 16, within half of your weekly limit. Keep in mind that Fable models use up limits faster than other Claude models.
- If you call Fable through the API, check whether your code edits conversation history: such requests now return a 400 error by default.
- Every number so far comes from Anthropic and its partners. The UK AI Security Institute, Frontier Design and METR tested the model before release, but, as the company itself notes, they reviewed neither the announcement nor the system card and may not agree with their conclusions. We will add independent measurements to this article as they appear.
More model news and reviews are under our LLM tag.