Skip to content
    Neurohive
    • News
    • Open LLMs
    • AI agents
    • Local models
    • Image & video
    RU

    Topics

    • Open LLMsOpen-weight models compared: quality, price and how to pick one
    • AI agentsAgents for coding, research and computer use: frameworks, benchmarks, comparisons
    • Image & videoImage and video generation and editing: models and services
    • Local modelsRunning models on your own hardware: VRAM, quantization, inference
    • ArchitecturesHow neural networks work: from CNNs to transformers and MoE
    • BenchmarksWhat benchmarks measure and how to read launch-day numbers
    • World modelsWorld models, 3D scenes and robots: demos, code, what you can run
    • Proprietary modelsGPT, Gemini, Claude and other closed-weight models: pricing, tests, reviews

    Sections

    • State-of-the-Art
    • AI Apps
    • Popular networks
    • Datasets

    Neurohive

    • Contact Us
    News Open LLMs AI agents Image & video Local models Architectures Benchmarks World models Proprietary models
    Neurohive
    News›

    Topics

    • Open LLMs
    • AI agents
    • Image & video
    • Local models
    • Architectures
    • Benchmarks
    • World models
    • Proprietary models

    Sections

    State-of-the-Art AI Apps Popular networks Datasets

    Neurohive

    Contact Us
    Русский

    Computer Vision

    20 November 2026 AI agents

    WeVisForensics: Tencent’s Open AI Agent Detects AI-Generated Videos with 95.2% Accuracy

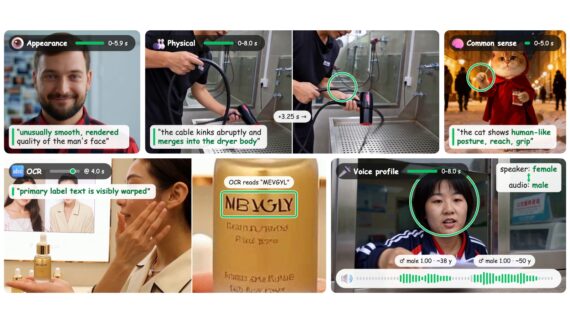
    Researchers from Tencent’s WeChat Vision team and Nanjing University have introduced WeVisForensics, an AI agent for AI-generated video detection. A main agent picks from six experts for appearance, physics, common…
    Hugging Face
    12 November 2026 Architectures

    Semantic Segmentation: How It Works, From U-Net to Segment Anything

    Semantic segmentation is the computer vision task of assigning a class label to every pixel of an image: this pixel is road, that one is a pedestrian, those are sky.…
    7 November 2026 Image & video

    Image Super Resolution: How AI Upscaling Works, From SRCNN to Diffusion

    Image super resolution is the task of turning a low-resolution image into a sharper, higher-resolution one. It is what an “AI upscaler” does when it enlarges an old photo, what…
    26 October 2026 Benchmarks

    StreamEval: The Best Streaming Video Generation Model Completes Only 15% of Reference Edits

    Researchers from Tsinghua University, NVIDIA, CMU, UC Berkeley, Princeton, NUS and Reactor released StreamEval, a benchmark that measures how well streaming video generation handles real-time interaction: can a model execute…
    Hugging Face
    26 October 2026 Architectures

    Generative Adversarial Networks (GANs): How They Work, With PyTorch Code

    A generative adversarial network (GAN) is a generative model made of two neural networks trained against each other. The generator turns random noise into fake data, such as images; the…
    26 October 2026 AI Apps

    From Video Storage to Video Intelligence: How AI Is Transforming Cloud Surveillance Systems

    Security cameras have become excellent at recording events. Finding useful information in those recordings, however, remains a challenge. Consider a business operating 100 security cameras at 2 Mbps each. Recording…
    25 October 2026 Architectures

    Convolutional Neural Networks (CNN): How They Work, Step by Step

    A convolutional neural network (CNN, or ConvNet) is a type of neural network designed for data with a grid structure, above all images. Instead of connecting every input pixel to…
    14 October 2026 Open LLMs

    VideoJev: Open Model Answers Questions About Video as Accurately as Thinking Mode, but 100 Times Faster

    Researchers from Nanjing University, JD.com, and six other Chinese universities introduced VideoJev, a family of models for video question answering. They answer about 100 times faster than models in Thinking…
    Hugging Face
    13 October 2026 World models

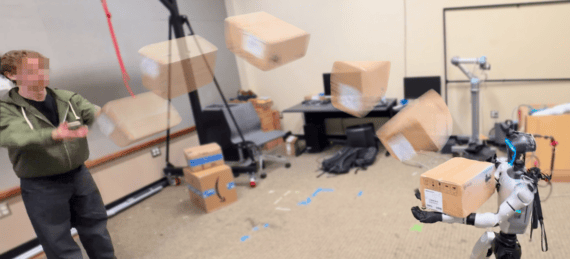
    Humanoid Robot Catches Thrown Boxes up to 2 kg From up to 7 Meters Using Only Its Camera

    Researchers from the University of Washington, USC, the National University of Singapore, UNC Chapel Hill, and the Allen Institute for AI taught the Unitree G1 humanoid robot to catch thrown…
    19 August 2026 Computer Vision

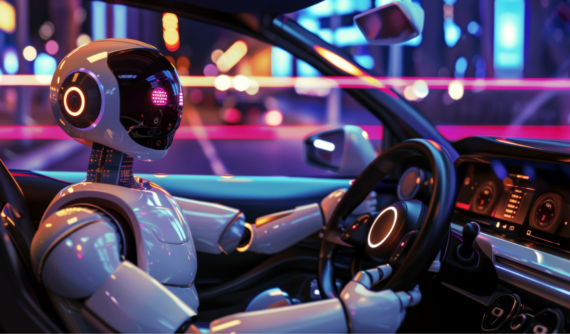
    How Artificial Intelligence in Cars Is Transforming Driver Training

    Learning to drive is seen as a straightforward process. A student studies the rules of the road, spends time behind the wheel with an instructor, practices different situations and eventually…
    3 August 2026 World models

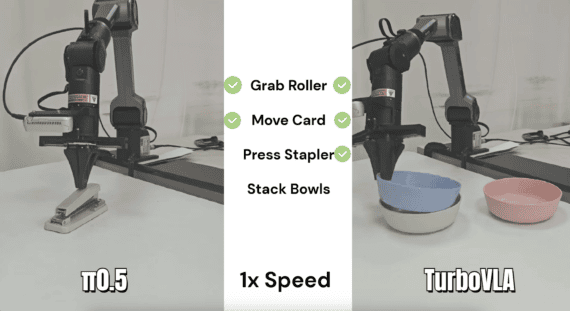
    TurboVLA: Robot Gets Commands Several Times Faster at a 97% Success Rate Thanks to Swapping the LLM for BERT

    Researchers from Huazhong University of Science and Technology and Huawei have released TurboVLA, a compact vision-language-action model that produces robot actions in 31.2 ms on a consumer-grade RTX 4090 and…
    Hugging Face
    28 May 2026 Open LLMs

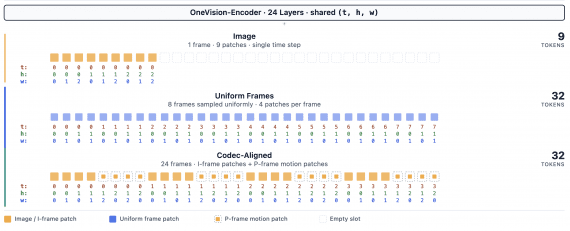
    LLaVA-OneVision-2: Multimodal Model Analyzes Compressed Video Stream Through a Codec Instead of Frame Sampling

    Researchers from Glint Lab, AIM for Health Lab, and MVP Lab published LLaVA-OneVision-2 (LLaVA-OV-2) — a next-generation multimodal model that rethinks how a neural network “watches” video. Instead of slicing…
    Hugging Face
    15 April 2026 AI agents

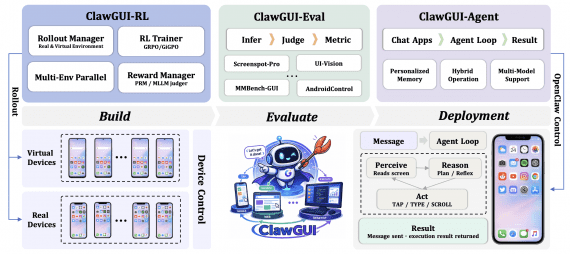
    ClawGUI: the first open-source end-to-end framework for GUI agents — from training to real device

    Researchers from Zhejiang University have published ClawGUI — a fully open-source framework for building GUI agents that control applications through their visual interface, just like a human would: taps, swipes,…
    18 December 2025 Benchmarks

    AI Models Are 13% Worse Than Humans at Detecting Generated ASMR Videos

    Researchers from CUHK, NUS, University of Oxford, and Video Rebirth introduced Video Reality Test — the first benchmark that tests whether modern AI models can create videos indistinguishable from real…
    6 August 2025 World models

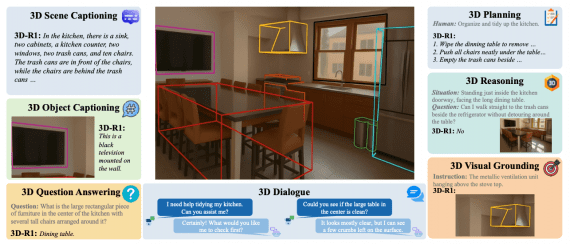
    3D-R1: Open Source Reasoning Model for 3D Scenes Outperforms State-of-the-Art Methods by 10% on 3D Benchmarks

    Researchers from Shanghai University of Engineering Science and Peking University presented 3D-R1 — a new foundation model that significantly improves reasoning capabilities in three-dimensional vision-language models (VLM). The model demonstrates an average performance…
    19 May 2025 World models

    NVIDIA Isaac 5.0: Enhanced Sensor Physics and Expanded Synthetic Data Generation

    NVIDIA continues to push the boundaries of AI-driven robotics with significant updates to its Isaac ecosystem, announced at COMPUTEX 2025. These innovations address key challenges in robotics development by enhancing…
    27 November 2024 State-of-the-Art

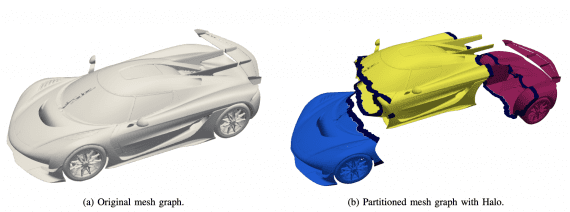
    X-MeshGraphNet: NVIDIA’s Scalable Solution for Physics Simulation Using Graph Neural Networks

    NVIDIA researchers have introduced X-MeshGraphNet, a novel extension of MeshGraphNet that addresses key scalability and practical limitations in physics simulation. The open-source framework, now available through NVIDIA Modulus, enables efficient…
    26 September 2024 State-of-the-Art

    Molmo: Open Source Multimodal Vision-Language Models Outperform Gemini 1.5 and Claude 3.5

    Molmo is a new series of multimodal vision-language models (VLMs) created by researchers at the Allen Institute for AI and the University of Washington. The Molmo family outperforms many state-of-the-art…
    4 July 2024 AI Apps

    How AI Helped King Studio Develop 13,755 Levels for Candy Crush Saga

    King, the developer behind the popular mobile game Candy Crush Saga, actively integrates artificial intelligence into the game’s development and optimization process. In a recent interview, Sahar Asadi from AI…
    12 May 2024 AI Apps

    NVIDIA DrEureka Model Accelerates Robot Training Faster Than Humans

    NVIDIA has demonstrated that large language models can expedite robot training. Robots with four limbs trained using the DrEureka model outperform standard learning systems by 34% in real-world movement speed…
    23 December 2023 State-of-the-Art

    VideoPoet: Google’s Language Model for Video Generation and Editing

    Google has unveiled VideoPoet, a language model for multimodal video content processing capable of turning text and images into clips, styling pre-existing videos, and generating soundtrack for them without any…
    12Older →
    Neurohive

    Neurohive — AI news. Open models, guides, reviews and comparisons.

    Topics

    • Open LLMs
    • AI agents
    • Image & video
    • Local models
    • Architectures
    • Benchmarks
    • World models
    • Proprietary models

    Sections

    • News
    • State-of-the-Art
    • AI Apps
    • Datasets
    • Popular networks

    Neurohive

    • Contact Us
    • Русская версия
    • RSS
    © 2018–2026 Neurohive Neural network news and research